RecurrMoE: adaptive intelligence.
A 1.03B-parameter architecture featuring hierarchical dual-level routing, embedded sparse Mixture-of-Experts, virtual-layer KV mapping and entropy-regularised exit masking. Pretrained on 12B tokens across a three-phase curriculum, it decides token by token how much computation each word needs.
- Compute reductionRealised at deployment
44.4%44.4% - Memory reductionvs. 2D parallel masking
93.7%93.7% - Virtual expert pathsFrom 4 physical experts
3636 - Pretraining tokensThree-phase curriculum
12B12B
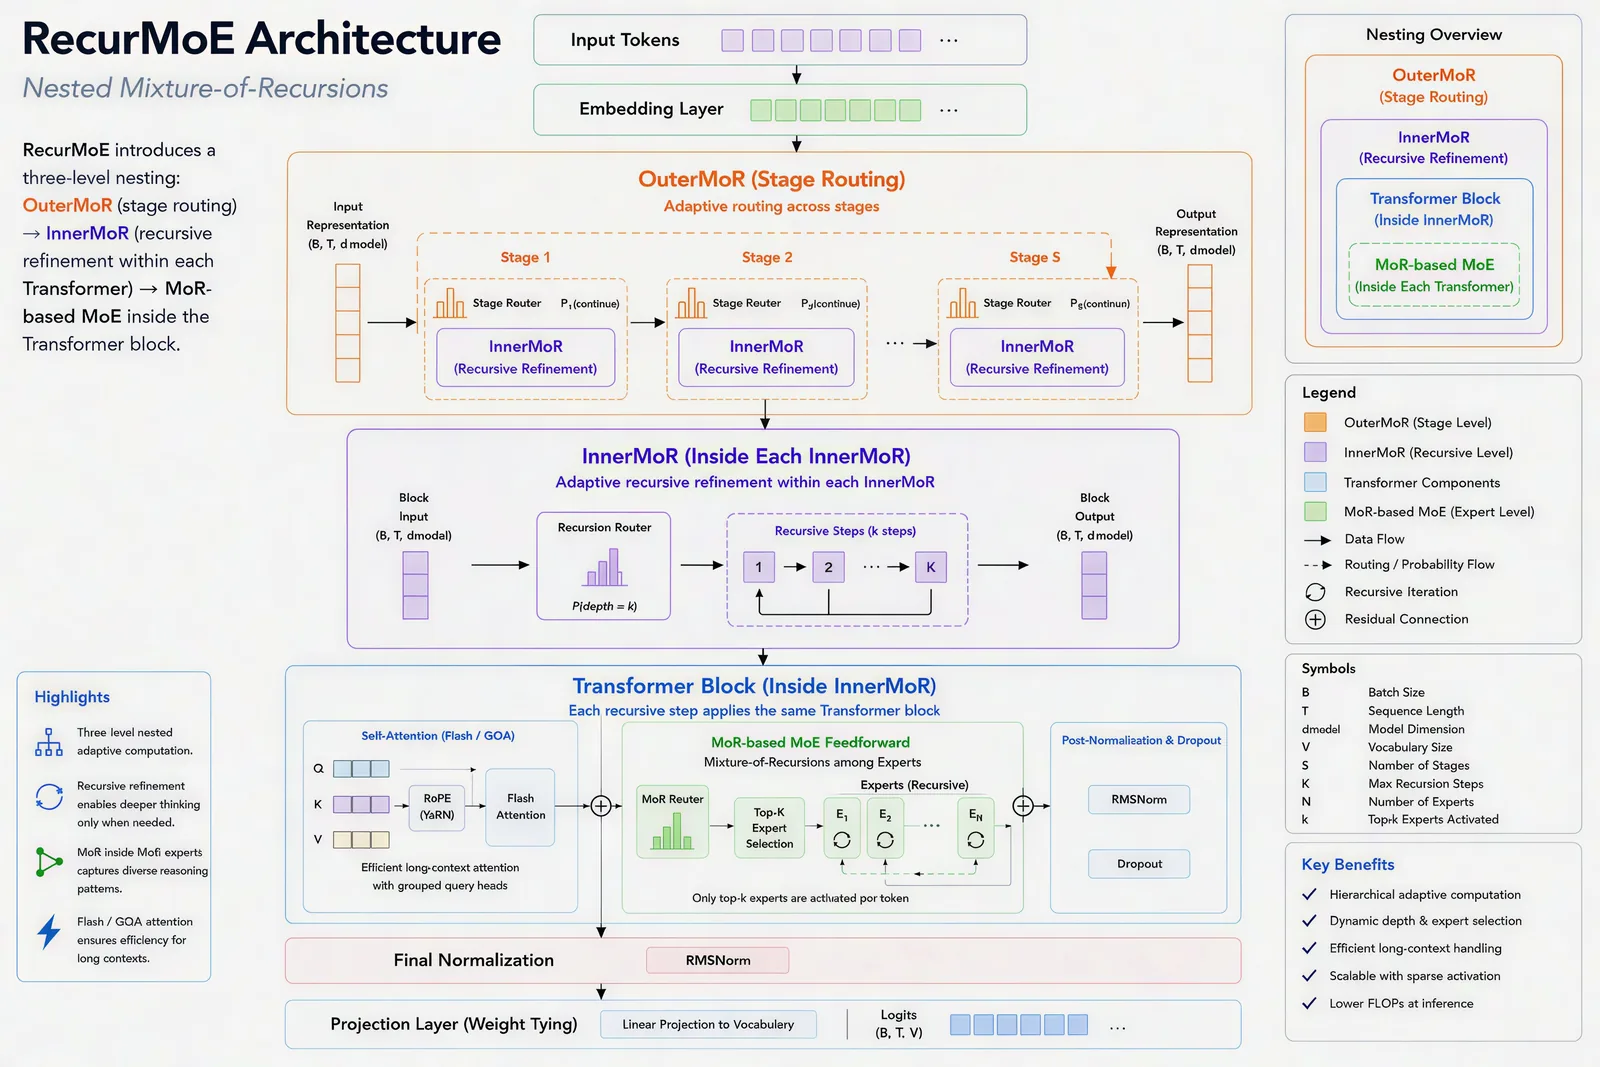
Three nested levels of adaptive computation.
Outer stage routing decides when a token can exit; inner recursion decides how many times to refine it; sparse experts decide which parameters to use.
Six ideas behind RecurrMoE.
Hierarchical dual-level routing
Separates local refinement (inner depth loops) from global token exiting (outer stage gates), optimising depth and stage budget independently.
Embedded sparse MoE
A top-2 SwiGLU expert network inside the recursive block routes tokens through time and space — 36 virtual expert paths from 4 physical experts.
Virtual-layer KV mapping
Resolves the recurrent KV-cache overwrite bottleneck with a unified virtual index V = p · d_max + d, keeping training and inference in strict parity.
Exit-stage validity masking
Dynamic validity masks isolate early-exited tokens from deep attention gathers, preventing out-of-distribution logit corruption.
Progressive context ramp
Scales the effective context window from 2,048 to 8,192 tokens through a three-phase curriculum with NTK-by-parts rotary interpolation.
93.7% memory reduction
Removes the quadratic O((T·D)²) overhead of 2D parallel masking, restoring standard O(T²) attention.
Measured, honestly.
Deployment configuration of RecurrMoE-1B, as reported in the paper.
Benchmark accuracy
| Benchmark | Accuracy |
|---|---|
| MMLU | 24.83% |
| ARC | 21.08% |
| HellaSwag | 25.90% |
| WinoGrande | 49.41% |
| TruthfulQA | 8.57% |
| Average | 25.96% |
Efficiency
- Total parameters
- 1.03 billion
- Mean exit stage
- 5.01 / 9 stages
- Effective depth
- 10.0 / 18 layers
- Inference mode
- Token-level early exit
Where we’re headed.
From foundational research to production-ready adaptive AI systems.
Phase 1 — Foundation · Completed
RecurrMoE-1B architecture & pretraining
Designed the hierarchical architecture and pretrained it on 12B tokens across a three-phase curriculum on 2× NVIDIA A100 80GB GPUs.
Phase 2 — Publication · Completed
Research paper & open-access release
Published the paper on Zenodo with full methodology and benchmark results.
Phase 3 — Scale up · In progress
RecurrMoE-7B & enhanced training
Scaling to 7B parameters with extended pretraining across multi-node GPU clusters and greater expert diversity.
Phase 4 — Production · Upcoming
Inference engine & API platform
A production inference engine with optimised virtual-layer KV cache, expert parallelism and a developer API.
Phase 5 — Ecosystem · Upcoming
Open-source toolkit & community
Open-source release of the training framework, pretrained checkpoints and evaluation tools.
Open, citable, reproducible.
Authors: Bala Murugan, Deepak, Daniel Joe, Sudalai, Muthu Siva. DOI 10.5281/zenodo.20570332.
@misc{recurrmoe2026,
  title     = {RecurrMoE: Hierarchical Adaptive Computation via Nested
               Mixture-of-Recurrence and Sparse Expert Integration},
  author    = {Bala Murugan and Deepak and Daniel Joe and Sudalai and Muthu Siva},
  year      = {2026},
  month     = jun,
  publisher = {Zenodo},
  doi       = {10.5281/zenodo.20570332},
  url       = {https://doi.org/10.5281/zenodo.20570332}
}Build with a research-grade team
Tell us what you need. We reply within one business day with next steps.